November 2026 · Work in progress
Ahead-of-time neuron planning
Different tokens need different computation. I’m exploring a planner that selects eligible MLP neurons before the system needs their weights.
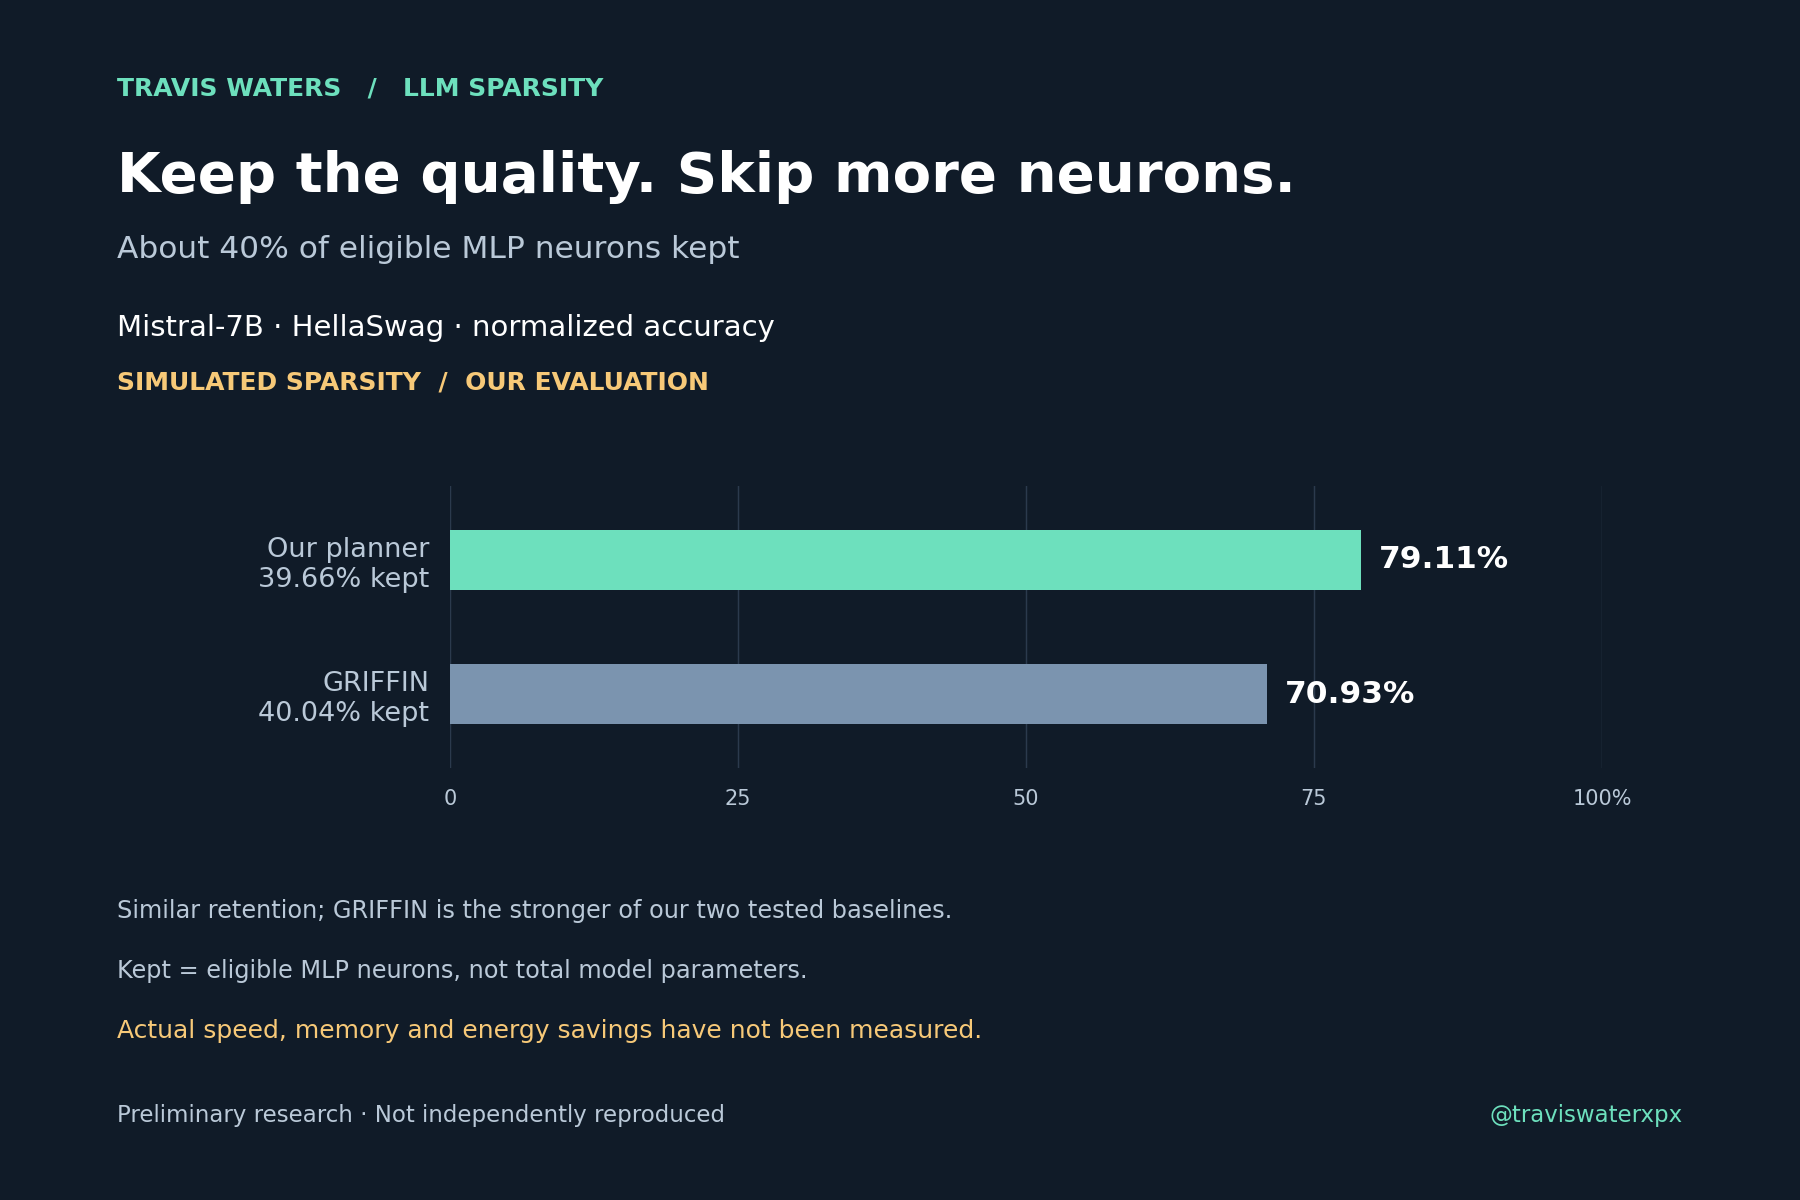
In our simulated Mistral-7B HellaSwag evaluation, the planner scored 79.11% at 39.66% retention, versus GRIFFIN’s 70.93% at similar retention. The dense model scored 81.18%.
Retention refers to eligible MLP neurons, not the whole model. Actual acceleration is still unmeasured.